Kimi K3.1 Pro: Specs, Pricing, Benchmarks and Who Should Use It
Last verified: October 28, 2026 (Asia/Shanghai). Facts come from Moonshot / Kimi's official blog, API docs, pricing page and X account linked below. Vendor benchmarks are labeled as such. Independent Artificial Analysis figures are cited separately. We have not run our own hands-on tests.
Kimi K3.1 is Moonshot AI's October 2026 flagship line — shipped first as Kimi K3.1 Pro (plus a Highspeed twin). It is a post-trained upgrade of Kimi K3: a 3T-class open-weight MoE with a 1-million-token context, native vision, and a stated push on coding, 3D/CAD, finance agents and long-horizon tool use. API IDs are kimi-k3.1-pro and kimi-k3.1-pro-highspeed. Full weights are promised by November 4, 2026 — as of this writing they are not downloadable yet. This guide covers what shipped, what it costs, which benchmarks are vendor-reported vs third-party, and who should try it now.
| At a glance | Kimi K3.1 Pro |
|---|---|
| Maker | Moonshot AI (Kimi) |
| Release | October 23–24, 2026 (tech blog, CN news) |
| Class | 3T-class MoE; official X thread: 2.8T total / 104B active, multimodal (announcement) |
| Context | 1,048,576 tokens (pricing docs) |
| API model IDs | kimi-k3.1-pro, kimi-k3.1-pro-highspeed |
| API price (per 1M tokens) | Pro: $2 in / $10 out; cache write $2; cache hit $0.20. Highspeed: $4 / $20; cache write $4; cache hit $0.20 (platform home) |
| Thinking | Always on; reasoning_effort: low / high / max (API default max) (quickstart) |
| Where to use | kimi.ai, Kimi apps, Kimi Work ≥3.1.0, Kimi Code (/model), Kimi API |
| Open weights | Promised by Nov 4, 2026; not public as of Oct 28, 2026 |
Sources: Kimi K3.1 Pro tech blog, API quickstart, platform pricing cards.
Practical rule: treat "Kimi K3.1" as the series name and K3.1 Pro as the model you actually call. Until November 4, "open-weight" is a shipping promise, not a Hugging Face download.
What Kimi K3.1 Pro is
Moonshot's English tech blog and Chinese launch note describe K3.1 Pro as the first model in the K3.1 series and their most capable 3T-class open-weight model to date. It is not a new pretrain from scratch: it is a post-trained Kimi K3 with "substantially larger post-training compute," including large-scale joint RL across many downstream domains.
The same launch ships Kimi K3.1 Pro Highspeed — same intelligence, about 2–3× output speed (Moonshot's claim), at roughly 2× API token prices except cache hits, which stay $0.20/MTok.
Availability channels listed by Moonshot:
- Consumer chat: kimi.ai and mobile apps (iOS, Android, HarmonyOS)
- Desktop agent: Kimi Work 3.1.0+
- Coding product: Kimi Code via
/model - Developers: Kimi API Platform with OpenAI-compatible
https://api.moonshot.ai/v1 - Enterprise: Kimi Business / Enterprise — admins must enable K3.1 Pro (off by default at launch)
Kimi Code membership note (product docs, not API): K3.1 Pro on Plus / Moderato and above; up to 1M context and Highspeed on Pro / Allegretto and above (What's New).

Availability and pricing
API (pay-as-you-go)
From the Kimi API platform price cards and pricing explanation:
| Model | Input / MTok | Output / MTok | Cache write / MTok | Cache hit / MTok |
|---|---|---|---|---|
kimi-k3.1-pro | $2.00 | $10.00 | $2.00 | $0.20 |
kimi-k3.1-pro-highspeed | $4.00 | $20.00 | $4.00 | $0.20 |
kimi-k3 (previous flagship) | $3.00 | $15.00 | $3.00 | $0.30 |
Billing notes from the quickstart FAQ:
- Flat pricing across the full 1M context — no length tiers.
- Context caching is automatic; TTL defaults to 5m, optional 1h.
- Flagship unlock: successful top-up of at least $1; cumulative top-ups drive rate-limit tiers.
- Zero Data Retention is available for API customers (Moonshot's claim on the tech blog).
For context, Simon Willison notes the Pro rate matches GPT-6.1 Sol and is about half Claude Opus 5.5's per-token price (his Oct 23 write-up). That is a price comparison only — not a quality claim.
Product / membership
Consumer and Code access are subscription-gated by plan tier (see Kimi Code docs above). On Oct 25, 2026, @Kimi_Moonshot apologized for rate-limit / quota issues on the K3.1 Pro subscription plan and announced a one-time usage reset restoring 25% of monthly quota for every subscriber.
Practical rule: if you need reproducible agent runs, budget for Highspeed only when latency matters. Cache hits are the real lever — Pro and Highspeed both bill cached input at $0.20/MTok.
Specs and API behavior
From the K3.1 Pro quickstart and model list:
- Inputs: text, images (base64 or
ms://…file IDs — public image URLs are not supported), and video via file upload. - Outputs: text (plus streamed
reasoning_content). - Thinking: cannot be disabled; set
reasoning_efforttolow,high, ormax(API defaultmax). Disabling thinking returns HTTP 400 in Kimi Code. max_completion_tokens: default 131,072; up to 1,048,576.- Fixed sampling:
temperature=1.0,top_p=0.95,n=1, penalties 0 — omit them. - Tools: function calling, dynamic tool loading, structured JSON Schema output, Formula official tools. Web search "is being updated and is not recommended" for production near-term.
- Client: OpenAI SDK against
base_url="https://api.moonshot.ai/v1"withMOONSHOT_API_KEY.
Minimal call (from official docs):
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["MOONSHOT_API_KEY"],
    base_url="https://api.moonshot.ai/v1",
)

completion = client.chat.completions.create(
    model="kimi-k3.1-pro",
    messages=[{"role": "user", "content": "Introduce Kimi K3.1 Pro in one sentence."}],
)
print(completion.choices[0].message.content)
Official (vendor-reported) benchmarks
Unless noted, scores below are Moonshot-reported from the tech blog, typically with reasoning effort max, temperature 1.0, top-p 0.95. Treat them as vendor claims until you reproduce them.
| Benchmark | Kimi K3.1 Pro | Notes (vendor) |
|---|---|---|
| Terminal-Bench 4.0 | 65.7% | Ahead of GPT-6 Astra 58.2%; behind Claude Opus 5.5 66.4% (Claude-Code harness) |
| Kimi Code Bench 3.0 Long-horizon (internal) | 61.2% | vs K3 55.95% |
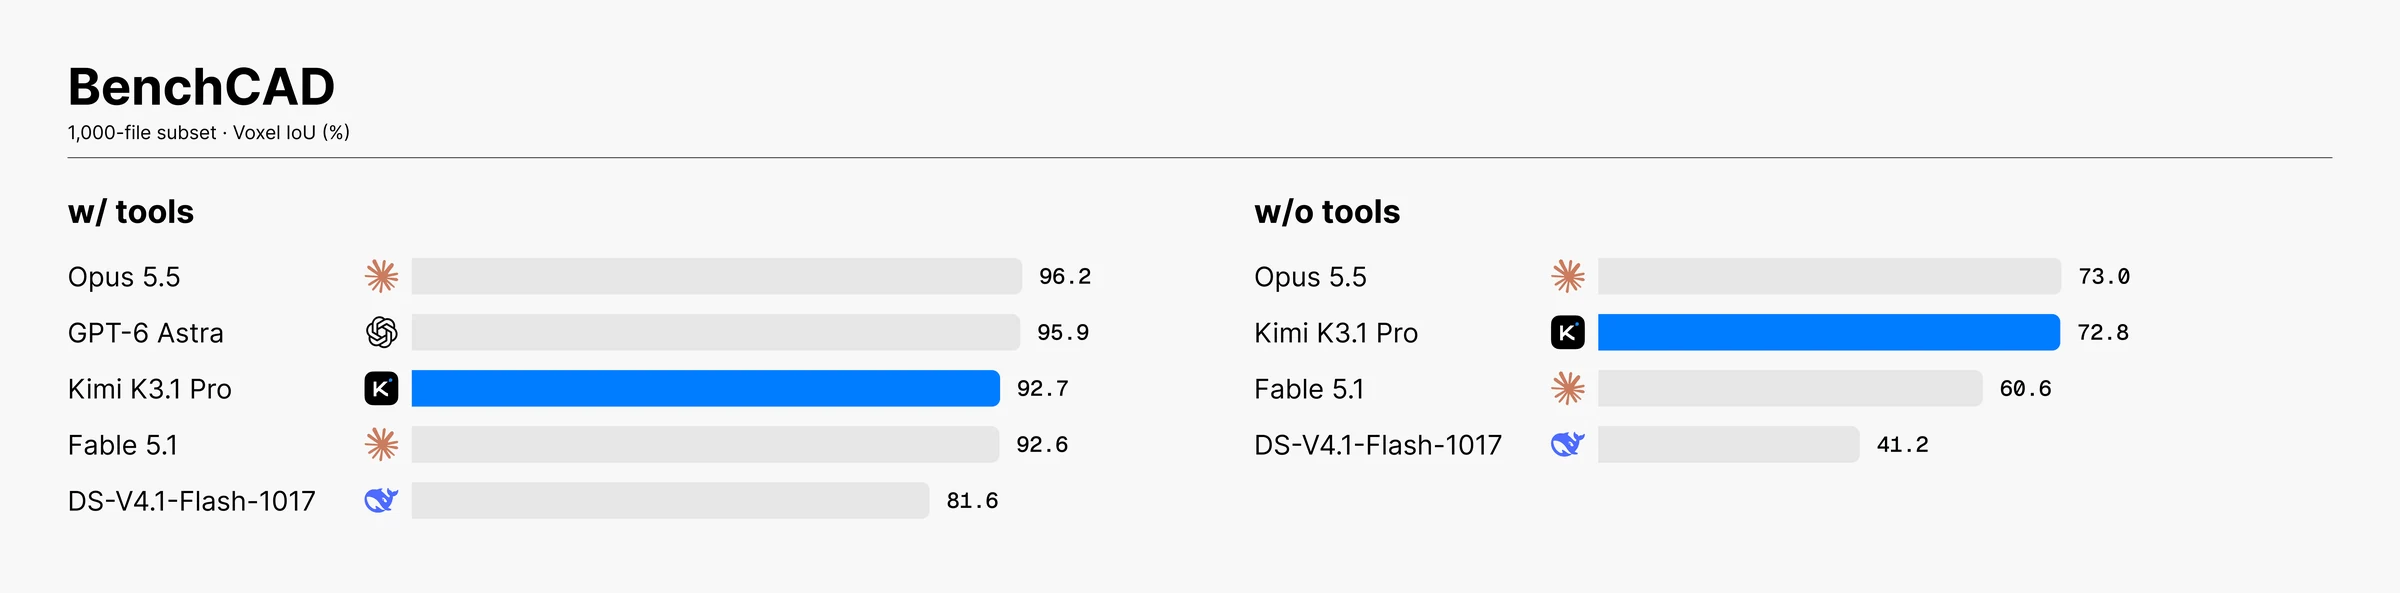
| BenchCAD (with tools) | 92.7% | vs Opus 5.5 96.2%, GPT-6 Astra 95.9% |
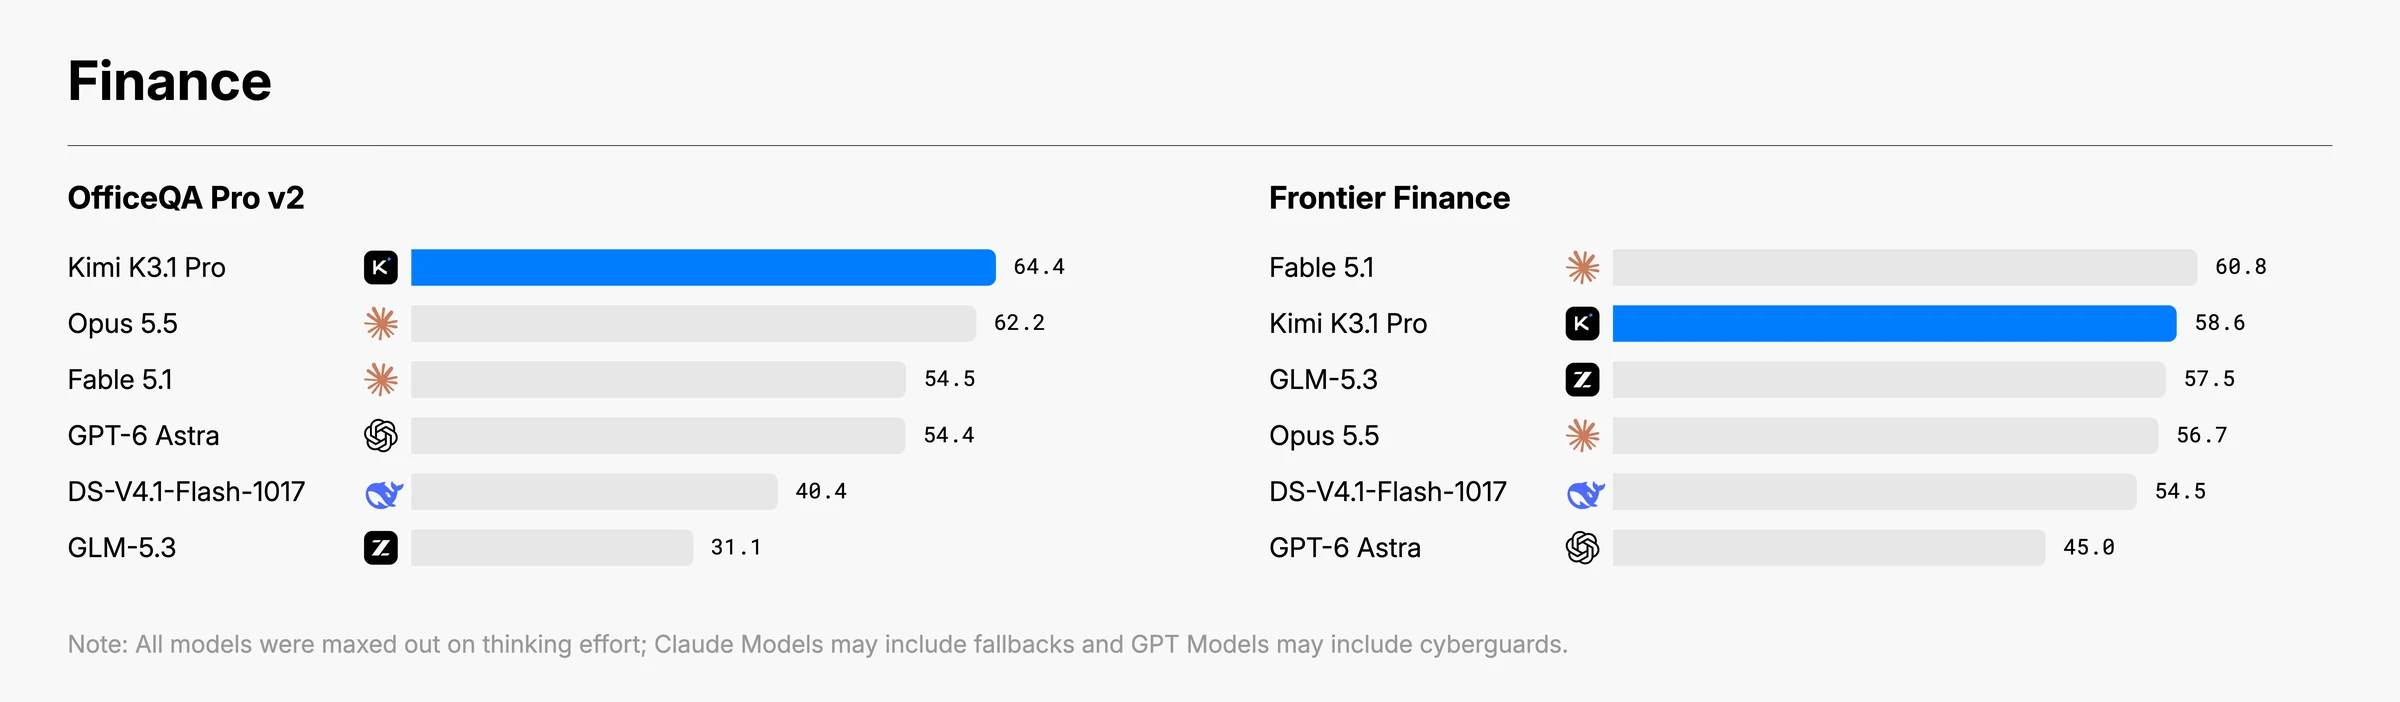
| OfficeQA Pro v2 | 64.4 | Moonshot calls this SOTA |
| Kimi Hallu Bench Hard (internal stress test) | Claim-level hallucination 8.3% (was 23.4% on K3) | Explicitly not overall daily error rate |
| xdev-bench-hard (internal cyber) | Final release 81.0% pass@3 | Unrestricted checkpoint 90.5%; Moonshot removed cyber training data for the open-weight path |
Internal finance deltas vs K3 (vendor): Financial Modeling +7.2 points; Financial Research +11.6 points; Business Operation about 4.2× K3.
Moonshot also documents a long-horizon coding demo: building a human walking simulator on human-atlas, then fixing 36 shoulder-muscle moment-arm bugs after reward shaping stalled — a vendor narrative, not an independent eval.
On cybersecurity, Moonshot argues it deliberately cut cyber-related mid-training and RL data so the open release would not extend the absolute offensive frontier, while still improving over K3 via general coding skill. That trade-off is contested on Hacker News (see below).
Independent signal: Artificial Analysis
Artificial Analysis currently lists Kimi K3.1 Pro at:
- Intelligence Index: 55 (#4 / 220 in their ranking snapshot)
- Output speed: 41.4 tokens/s (they call it notably slow vs a ~85 t/s median in-class)
- API price matching Moonshot: $2 / $10
- Cost per Intelligence Index task: about $2.11
- Context: 1M; text + image in, text out
- Status on AA as of this check: labeled proprietary (weights not public yet)
Simon Willison summarized AA as ahead of Claude Fable 5.1, GPT-6 Astra and Gemini 4 Argon (all 53 on his write-up) and behind only Claude Opus 5.5 (58) — "the first time a (soon-to-be) open weight model has scored this highly against the frontier" (Oct 23).
Practical rule: use Moonshot's charts for what they optimized, AA for a third-party composite, and your own 20–50 tasks for ship / don't ship.
Early real-world reactions
Hacker News. The main thread Kimi K3.1 Pro and K3.1 Pro Highspeed passed 1,091 points with hundreds of comments within days. Themes we verified in the thread:
- Surprise that an open-weight-bound model sits near Opus 5.5 on Terminal-Bench (with the usual "wait for AA" caveat — AA later posted 55).
- Praise for the Hallu Bench Hard drop (23.4% → 8.3%), with the stress-test caveat.
- Split on cyber data removal: some call it "lame," others welcome slower diffusion of exploit skill.
- Reminder that weights land November 4, not on launch day.
A related AA discussion: Kimi K3.1 scores 55 on Artificial Analysis (121 points).
X / developer notes (verbatim excerpts after reading the posts):
- @Kimi_Moonshot: "Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal."
- @Letta_AI: "We've added GPT-6.1 Terra, Kimi K3.1 Pro and DeepSeek V4.1 Flash to the FrontierMemory leaderboard. Kimi K3.1 Pro ties Opus 5.5 and GLM-5.3 for #1…"
- @gmi_cloud: "Tested Kimi K3.1 Pro and Claude Opus 5.5 on the same prompt: creating a beautiful, highly detailed Japanese pixel-art street corner. Kimi K3.1 Pro is a cheaper alternative, though it's not at Opus 5.5 quality yet."
- @One2xDatalab reported a timed 3D-style task: "Opus 5.5 — 17 | 21.0 | $4.51 / DeepSeek V4.1 — 15 | 5.3 | $0.071 / Kimi K3.1 Pro — 19 | 43.1 | $1.90" and noted runs were "Not pure end-to-end."
Hands-on video (third-party). Matthew Berman's review mixes strong demos with accuracy misses:
Watch on YouTube: "They actually did it... (Kimi K3.1)" by Matthew Berman
Third-party video by Matthew Berman, an independent creator. AI Takeaway did not make this video and is not affiliated with its creator.
No time to watch the whole review? AI Takeaway is a tool that works on any YouTube video, including third-party reviews like this one. Paste the link to get the key points in minutes, jump to the original timestamps, and ask follow-up questions; every answer cites the video. You can also browse the Hub for more AI and tech interviews.
Who should use Kimi K3.1
- API builders who want frontier-ish coding/agents near Sol pricing: $2/$10 with 1M context and strong vendor + AA signals.
- Teams already on Kimi K3: K3.1 Pro is cheaper per token than K3 ($2/$10 vs $3/$15) with claimed quality gains — migrate after smoke tests; start a new session when switching models (Kimi Code guidance).
- 3D / game / CAD workflows: Moonshot demos Blender, Unreal, Godot and BenchCAD; verify on your asset pipeline.
- Finance research agents that need long docs: vendor SOTA claim on OfficeQA Pro v2 and lower stress-test hallucination — still require human audit.
- Self-hosters after Nov 4: wait for weights, license terms and VRAM reality for a 2.8T-class MoE.
- Probably not first pick if: you need maximum tokens/sec (AA ~41 t/s on Pro), must disable thinking, depend on production web search today, or need offensive cyber capability Moonshot intentionally cut.
How it compares (short)
| Lens | Takeaway |
|---|---|
| vs Kimi K3 | Same class; more post-training; lower API price; vendor gains on coding/finance/hallucination stress tests |
| vs GPT-6.1 Sol | Same $2/$10 list price band; different strengths — see our Sol vs Astra guide |
| vs GPT-6 Astra / Gemini 4 Argon / Muse Wonder | Moonshot claims parity-ish on selected agent/coding benches; AA puts K3.1 Pro slightly ahead of Argon on the composite Index — still not a substitute for task tests (Gemini 4 Argon, Muse Wonder) |
| vs DeepSeek V4.1-Flash-1017 | Flash is far cheaper per token and already open MIT; different trade-offs — our Flash-1017 guide |
| Voice / realtime | Unrelated product category — see Grok Voice 3.0 if that is your need |
Getting started checklist
- Create a Moonshot API key and set
MOONSHOT_API_KEY. - Point an OpenAI-compatible client at
https://api.moonshot.ai/v1withmodel="kimi-k3.1-pro"(or-highspeed). - Leave thinking on; pick
reasoning_effort(low/high/max) per latency/quality budget. - Prefer cache-friendly system prompts; set
prompt_cache_options.ttlto1hif calls are spaced out. - For Kimi Code, start a new session before switching from K3 / K2.x models.
- Run 20–50 of your tasks; track pass rate, tokens, wall time and $ — do not ship on vendor charts alone.
- If you need open weights, calendar November 4, 2026 and re-check the tech blog / Hugging Face for the actual files and license.
Keep up without the watch time
Model launches are weekly now. If you would rather read than watch, the AI Takeaway video summary hub has free curated summaries of AI and tech interviews, for example:
- Muse Wonder: Zuckerberg and Wang's $100B AI
- Sam Altman on Astra, AGI, and the future of OpenAI
- Gavin Baker on Orbital Compute, TSMC, and Frontier Models
To keep up with ongoing AI news, check the Hub regularly. You can also install the AI Takeaway Chrome extension to get key points right on YouTube, or submit any YouTube video yourself on aitakeaway.net.
For more model guides, browse all AI Takeaway articles — including DeepSeek V4.1-Flash-1017, Gemini 4 Argon, GPT-6.1 Sol vs GPT-6 Astra, Muse Wonder, Grok Voice 3.0, Dessa Voice AI and Genie 4.
FAQ
What is Kimi K3.1?
Kimi K3.1 is Moonshot's October 2026 model series. The first shipped model is Kimi K3.1 Pro (and Highspeed), a post-trained 3T-class MoE with 1M context, available on Kimi products and the API as kimi-k3.1-pro.
How much does the API cost?
$2 per million input tokens and $10 per million output tokens for Pro; $4 / $20 for Highspeed. Cache hits are $0.20/MTok on both. Prices are flat across the 1M window (platform).
Is it open source / open weight yet?
Moonshot says full weights will be released by November 4, 2026. As of October 28, 2026 they are not public; Artificial Analysis still labels the API model proprietary.
Can I turn off chain-of-thought?
No. Thinking is always on. Lower reasoning_effort to low if traces are too long (quickstart FAQ).
How does it score on independent benchmarks?
Artificial Analysis reports an Intelligence Index of 55 and ~41 tokens/s on the first-party API (AA model page). Moonshot's own Terminal-Bench 4.0 figure is 65.7%.
Does it support images and video?
Yes for API vision (base64 / ms:// files) and video file uploads per the quickstart. Public image URLs are not accepted.
Sources
- Kimi / Moonshot, Kimi K3.1 Pro tech blog and Chinese launch post
- Kimi API, K3.1 Pro quickstart, model list, pricing explanation, platform home
- Kimi Code, What's New — K3.1 Pro
- @Kimi_Moonshot announcement thread and quota apology
- Artificial Analysis, Kimi K3.1 Pro
- Simon Willison, Introducing Kimi K3.1 Pro (Oct 23, 2026)
- Hacker News, launch thread and AA score thread
- X posts: Letta, GMI Cloud, One2x Datalab
- YouTube, Matthew Berman — They actually did it... (Kimi K3.1)